PrivacyLib: Privacy Controls at the Data Access Boundary
This latest deep dive into Meta's Privacy Aware Infrastructure (PAI) takes a look at PrivacyLib.
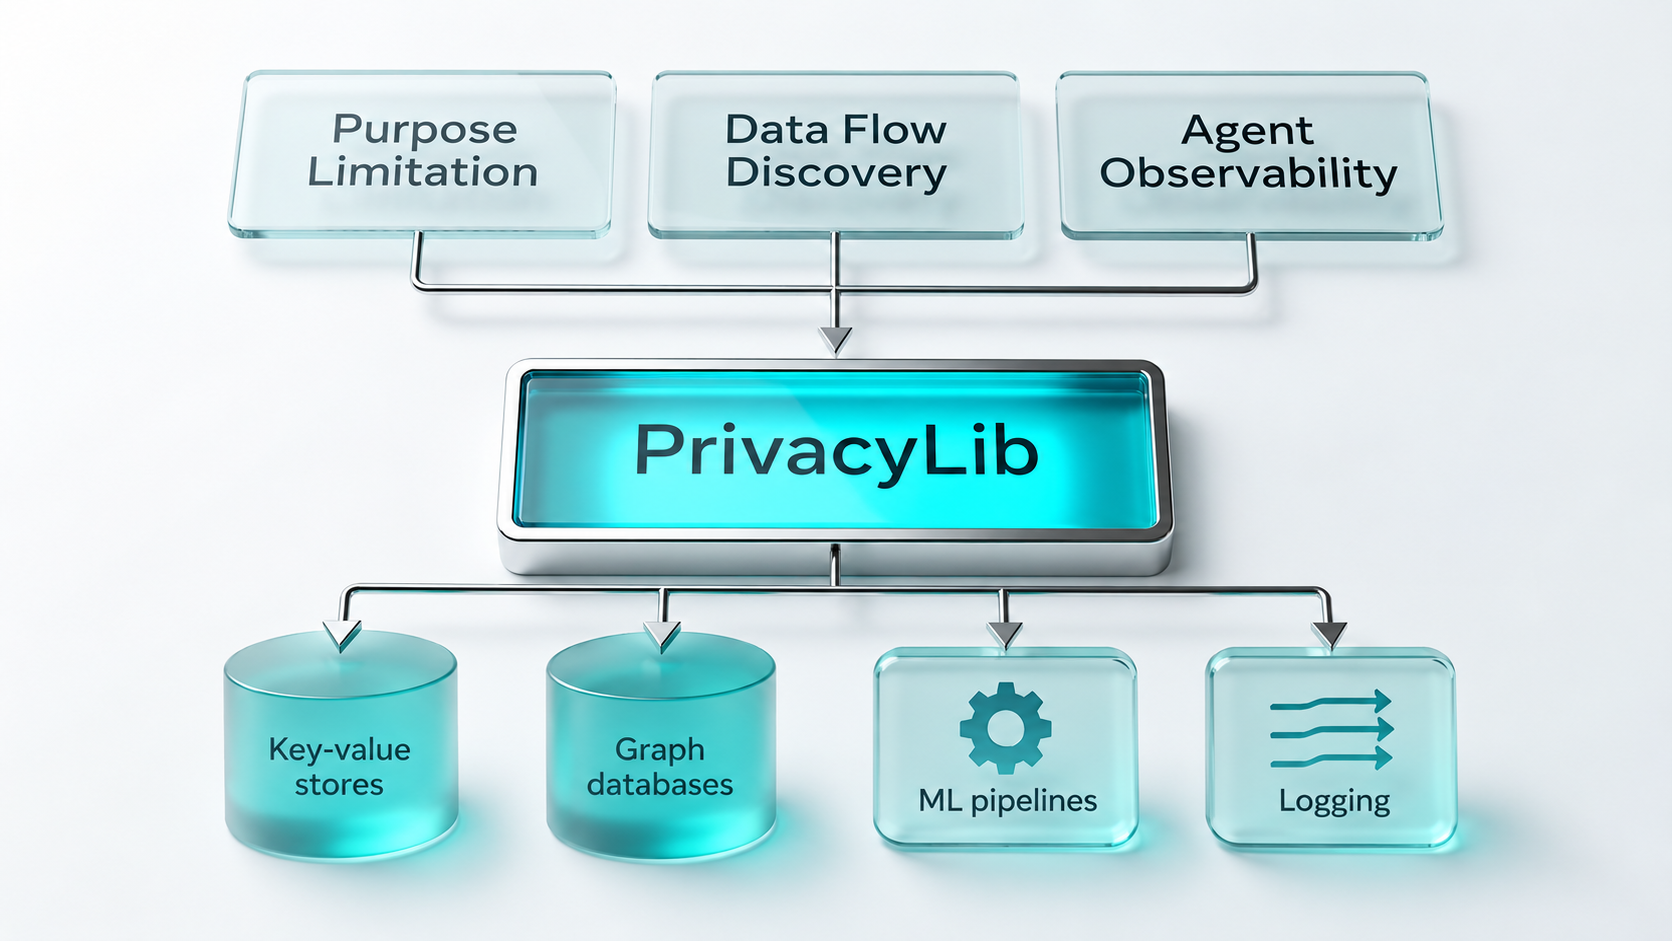
A privacy requirement must hold as data moves through Meta's diverse data and processing systems. Historically, supporting a new requirement meant implementing the same enforcement logic separately in each system. PrivacyLib replaces this with a common library that runs inside the clients of Meta's data and processing systems.
A system integrates with PrivacyLib once, and new privacy capabilities plug in as modules that reuse that integration. PrivacyLib performs billions of checks every second, and changes are simulated and rolled out per module.
For internal AI agents, whose data access paths may not be known in advance, tool calls on supported paths carry agent context to PrivacyLib. The propagated context links each access to its session, so modules can observe data use and block operations that are not allowed.
At Meta, many privacy requirements ultimately come down to the same question: Can we prove that a piece of data goes only where it is allowed?
At Meta's scale, rather than relying solely on manual privacy audits, which can go out of sync as systems change, we have developed Privacy Aware Infrastructure (PAI) to answer this question within the infrastructure itself. PAI offers efficient and reliable first-class privacy constructs embedded in Meta's infrastructure so that products can keep evolving quickly.
In previous posts, we have covered how data understanding, data lineage, and Policy Zones (our information flow control technology) play a role in PAI. Now, we are diving deep into PrivacyLib, a common library that runs inside the clients of hundreds of our data and processing systems at the point of data access.
PrivacyLib plays an important role in the final stage of the broader PAI workflow: continuously enforcing and monitoring data flows.
Before PrivacyLib, we integrated privacy enforcement separately into the clients of each data and processing system for each requirement. With this approach, implementing a new requirement across systems could take months.
Each new requirement, whether purpose limitation or data flow discovery, needed the same set of capabilities: covering a wide range of systems; deploying in weeks rather than months; running on every data access without becoming a latency problem; and rolling out enforcement changes without taking the fleet down. Over time, this approach became harder to scale as requirements and systems evolved.
PrivacyLib separates system integration from requirement implementation. We integrate each system once. When a requirement can be met at the point of data access, we implement it as a PrivacyLib module shared across the systems already integrated, so a new requirement no longer needs a separate implementation in each system.
There are two kinds of modules:
- Enforcing modules can block a data access. For example, Policy Zones enforces purpose limitation.
- Observing modules only record a data access. For example, Privacy Probes collects the runtime signals used to discover data flows.
As internal AI agents became a new way of accessing data, we also added the Agent Observability module to observe agent-related data access events and help safeguard the data that agents can reach. Systems already integrated with PrivacyLib picked it up without new integration work, which is what integrating once buys: each new privacy capability arrives as a module, not as a project.
Engineering Challenges and Approaches of PrivacyLib at Meta's Scale
PrivacyLib operates across a broad range of data access paths at Meta:
- More than a hundred libraries used to access data services, from key/value stores to AI features.
- Thousands of production services with versions of the deployed library.
- Millions of assets being accessed daily.
- Billions of checks every second.
Operating at this scale creates three engineering challenges:
| Challenge | Approach |
|---|---|
| Coverage: Systems can have multiple client libraries and legacy integrations, accept direct network calls, and offer direct database access to backing stores. All of them need to be handled to ensure requirements hold no matter the access path. | We integrate at two levels: typed client libraries, where PrivacyLib has full request context, and lower network boundaries on remaining RPC paths to get full coverage. Each integrated system maps its native APIs to PrivacyLib's common operations and provides the inputs required by its configured modules. Once those pieces are in place, the same module can be enabled in multiple systems without a separate system-specific integration. |
| Scale: At billions of checks per second, even a small per-check computational cost becomes consequential across the fleet. Every service in the hot path pays that cost. | We compile requirements at build time into their simplest evaluable form and answer most checks from caches inside the process, so the common path avoids a network call. |
| Reliability: Privacy logic runs in the hot path of critical systems, owned by teams that release on their own schedules. A change has to be testable in isolation and reversible on its own, because a fleet-wide rollback cannot be the recovery path. | Enforcement is deployed as part of the service that owns it, so a change reaches production through that service's own pipeline instead of a fleet-wide config push. |
Walkthrough: Protecting Messaging Metadata
To illustrate how everything comes together at Meta's scale, let's walk through a privacy requirement that needs to be upheld when processing messaging metadata.
Users exchange messages through apps like Messenger, which supports end-to-end encryption. As Messenger routes and delivers those messages, subject to applicable law, its backend systems process non-content messaging data (i.e., messaging metadata), such as information about when messages are sent or delivered, to improve product performance, detect abuse, and protect users from harmful conduct.
A variety of these backend services use Logger, a client library that runs in the service process, to write this metadata to data warehouse tables. Before writing a record, the PrivacyLib integration inside Logger invokes Policy Zones, an enforcing module, to check whether the metadata may flow to the destination table.
This check is broken down into two parts: what inputs need to be available to make a decision, and how the check is actually evaluated at runtime. After examining these two parts, we look at how PrivacyLib scales across systems and how changes roll out without disrupting the services in the path.
Annotating Messaging Metadata
Every Logger destination table has a LoggerConfig that describes the records written to it. MetadataTraceLoggerConfig defines one such configuration for message-delivery traces and marks it as containing messaging metadata:
final class MetadataTraceLoggerConfig extends LoggerConfigBase {
  use MessagingTrafficMetadataPolicyTrait;
  public function configure(
    LoggerFieldDefiner $fd,
  ): LoggerFieldDefiner {
    $this->annotateWithTableLevelPolicy();
    // Field and destination definitions
  }
}
A logging destination can have many writers, so the annotation describing its output data belongs to the destination rather than to each service that writes to it. If every service declared the annotation separately, the declarations could disagree, or a new writer could omit it entirely. Declaring it once in LoggerConfig gives every writer the same description of the data.
For this destination, MessagingTrafficMetadataPolicyTrait supplies the MESSAGING_TRAFFIC_METADATA table-level annotation, and annotateWithTableLevelPolicy() attaches it to the destination. LoggerConfig is Logger's own schema, and each system describes its data in its own format. To give PrivacyLib a single form to consume, Logger's code-generation pipeline translates the configuration into a PrivacyLib-compatible artifact.
The generated MetadataTraceLoggerConfigPrivacyLibArtifact is derived from MetadataTraceLoggerConfig and carries the destination identity and the messaging annotation:
/**
 * @codegen-source MetadataTraceLoggerConfig
 */
class MetadataTraceLoggerConfigPrivacyLibArtifact extends LoggerInputPrivacyLibArtifact {
  final public static function getAssetIDImpl(
  ): LoggerInputAssetID {
    return LoggerInputAssetID::get(
      'MetadataTraceLoggerConfig',
    );
  }
  protected static function getPurposePolicyVars(
  ): TPurposePolicyVars {
    return PurposePolicy::makeVars(
      TPurposePolicyName::MESSAGING_TRAFFIC_METADATA,
    );
  }
  // Other generated fields omitted.
}
The generated class above is used by Logger's client in Hack, Meta's typed PHP language. For its C++ and Python clients, Logger publishes destination identities and annotations to a central catalog. PrivacyLib uses that information to generate language-specific artifacts. In the C++ example in the next section, PrivacyLib uses the LoggerConfig name to load the C++ artifact for the destination.
Running the Check
The artifact from the previous section describes one Logger destination. PrivacyLib also needs to know what a Logger write means and which modules should run. Logger's Hack integration defines that once for all destinations:
$config->libraryConfig()->enablePrivacyLib(
  PrivacyLibOperation::write()
    ->input(
      PrivacyLibInput::instance(
        nameof ILoggerInputPrivacyLibPayloadProvider,
      ),
    )
    ->enforcements(
      PrivacyLibWriteEnforcement::zones(
        ZoneDataType::LOGGER,
      )->withPropagation()->enabled(),
      PrivacyLibWriteEnforcement::telemetryLogging()->enabled(),
      // Other modules
    ),
);
PrivacyLibOperation::write() declares PrivacyLib's write operation for Logger, and enforcements() lists the modules that run on it. The Policy Zones module can affect the result, while the Telemetry Logging module records the evaluation without affecting it. Adding a module here requires no changes to individual destinations or Logger call sites.
ZoneDataType::LOGGER tells Policy Zones that it is checking a Logger destination. In C++ services, Logger constructs the PrivacyLib request as follows:
const auto assetList = std::vector {configName};
PrivacyLibBuilder builder(
  "LOGGER_WRITE_CLIENT",
  assetList,
  LoggerWriteAPIEnumHelper::apiToHashedString(
    PolicyEnforcedLoggerWriteAPI::log),
  Caller::LOGGER,
  getLoggerWriteImplementation());
auto result = PrivacyLibRequest(std::move(builder)).dispatch();
PrivacyLib uses configName to load the destination's artifact. The hashed PolicyEnforcedLoggerWriteAPI::log value maps Logger's API to PrivacyLib's write operation. The remaining builder arguments identify Logger as the caller and provide the implementation that performs the write. dispatch() invokes the configured modules and records their outcomes.
For the Policy Zones module, PrivacyLib provides the destination annotations from the generated artifact and the current processing context. For this example, Policy Zones evaluates two conditions:
- The current context represents an allowed use of messaging metadata.
- The destination artifact carries the
MESSAGING_TRAFFIC_METADATAannotation.
When enforcement is enabled, the Policy Zones module denies the write if either condition fails. PrivacyLib combines the results from enforcing modules into one response. A denial stops the write before Logger sends the record downstream. Observing modules emit telemetry without affecting the response.
Scaling Privacy Checks Across Systems
PrivacyLib enables privacy checks to scale across heterogeneous systems through a common execution model, lightweight evaluation and telemetry, and coverage for requests that bypass integrated clients.
A Common Execution Model Across Systems
PrivacyLib's integrations span systems with very different APIs: key-value stores, graph databases, ML pipelines, filesystems, and logging systems like Logger. Each integration maps its access points to one of five common operations, and PrivacyLib invokes its modules at each:
- Read: runs when fetching data.
- Write: runs when storing data.
- RPC: runs when calling another service.
- Request entry: runs once when a service begins handling a request.
- Inline execution: wraps a specific computation inside a larger request, such as evaluating a feature. Data accesses made during that computation are evaluated using its inline privacy context.
Modules are written against these five operations rather than against each system's native API. Reads, writes, and RPCs also have post-operation variants, so observing modules can run after the access decision has been made. Once a system provides the mapping, every compatible module can reuse it, which is why enabling an additional module on an already-integrated system takes only days.
PrivacyLib runs inside the clients of data and processing systems because the clients already have the destination identity and request context that modules need. Keeping the evaluation in the same process avoids carrying those inputs across process boundaries on every access.
This design also has two advantages:
- Richer context: PrivacyLib can use the caller's identity, endpoint, and purpose while that information is still available. This information is frequently lost if the check is evaluated on the datastore.
- Failure isolation: A faulty change is contained to the service running that version of the code, keeping the shared datastore outside the failure boundary.
Keeping Checks Computationally Inexpensive
In-process evaluation must also be computa
Comments
No comments yet. Start the discussion.