Clice v1.0 Released: Welcome to Modern C++
clice recently hit 1,000 commits, a special milestone for the project.
Since July 19, 2026, clice has been shipping nightly builds and going through roughly four months of alpha testing, with a huge number of bugs fixed thanks to real-world feedback from early users.
Over the same stretch, I built a rigorous testing system for clice and ran extensive tests across many real open-source projects, tracking down and fixing the issues they uncovered.
What does that mean? Every core feature is now stable, and you rarely run into problems in day-to-day use. So I think the time is right to ship the first stable release.
The project looks very different today from where it stood two years ago in Design and Implementation of a New C++ Language Server, and this is probably the first time I’m promoting it widely, so please let me introduce it to you once again!
This is the project I have poured the past two and a half years into, the work I am proudest of, the one that has excited me the most and left me sad and anxious more times than I can count, and the most ambitious thing I have taken on in my short life.
What is clice?
In short, clice is a C/C++ language server written in modern C++, but it’s more than just a language server.
It is still built on LLVM/Clang, but unlike clangd and ccls, which are also Clang-based, clice was redesigned from the ground up to fix architectural problems that have gone unsolved in those servers for years.
It is written entirely in C++23 and serves as an example of modern C++ best practices in its own right, with all the major modern C++ features coming together remarkably well:
- Written entirely with C++20 coroutines, using our own libuv-based structured-concurrency async library for intricate asynchronous logic. It is a complex concurrent program running an event loop on the main thread while coordinating both multiple processes (IPC) and multiple threads.
- Written entirely with C++20 named modules and C++23
import std, and fully self-hosted: module wrappers for third-party libraries are generated automatically byclice modularize, and clice runs smoothly on its own codebase to provide module-aware language services. - Uses static reflection built on templates and C++20 concepts for all serialization and deserialization across formats, including TOML, JSON, bincode, blob, and command-line arguments, with Rust-macro-like declarative annotations and zero boilerplate.
- Data-oriented code design throughout, with almost no virtual functions outside the callback interfaces Clang requires. Makes heavy use of modern C++ APIs like
std::format,std::expected,std::ranges, andstd::views, steering clear of outdated legacy C++98/11 APIs. - A completely hermetic, reproducible build powered by Bazel, compiled with the unified xclang toolchain for a consistent cross-platform cross-compilation workflow. Compiled binaries are heavily optimized (PGO + LTO), and build artifacts depend on nothing beyond system libraries.
People are always debating whether modern C++ features like modules are actually ready for real work. clice’s answer is: yes, of course, completely usable! They hold up for complex software like clice, with hundreds of thousands of lines of code.
Maybe this is what the modern C++ we have been hoping for looks like. That said, the surrounding ecosystem really is inconvenient enough right now that getting this whole workflow running end to end took a huge amount of effort on my part to track issues and adapt everything.
Language Server
Here is an overview of clice’s main features:
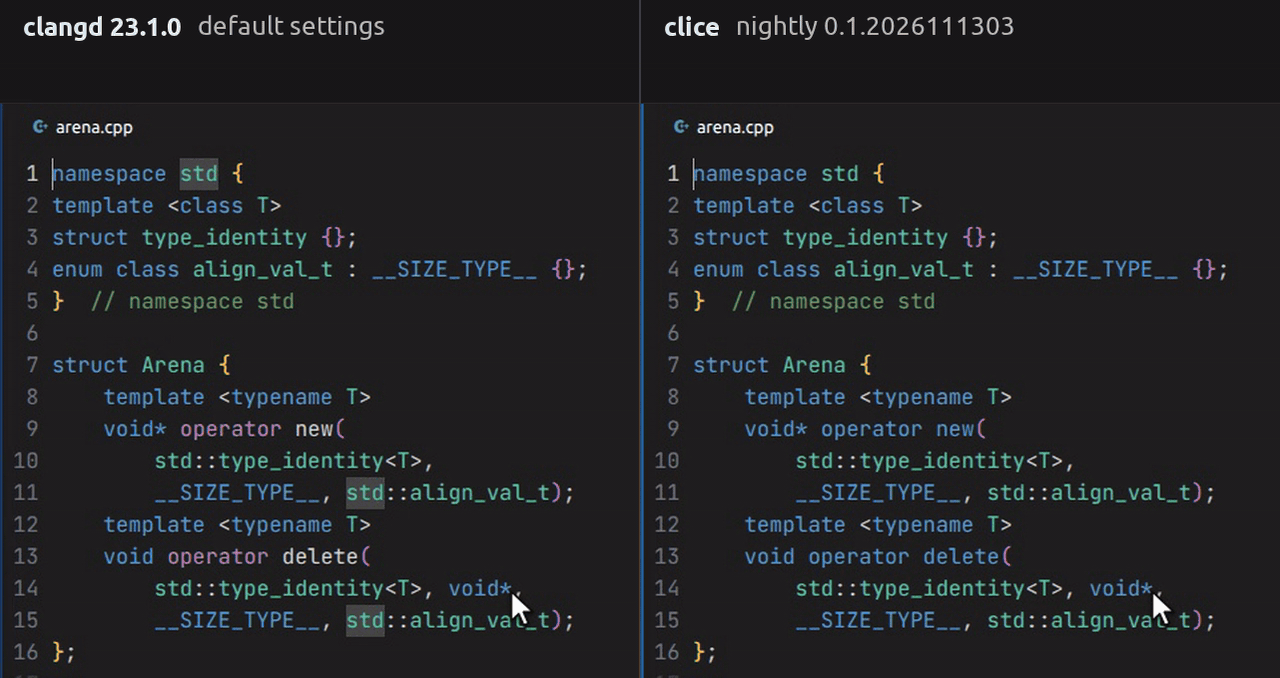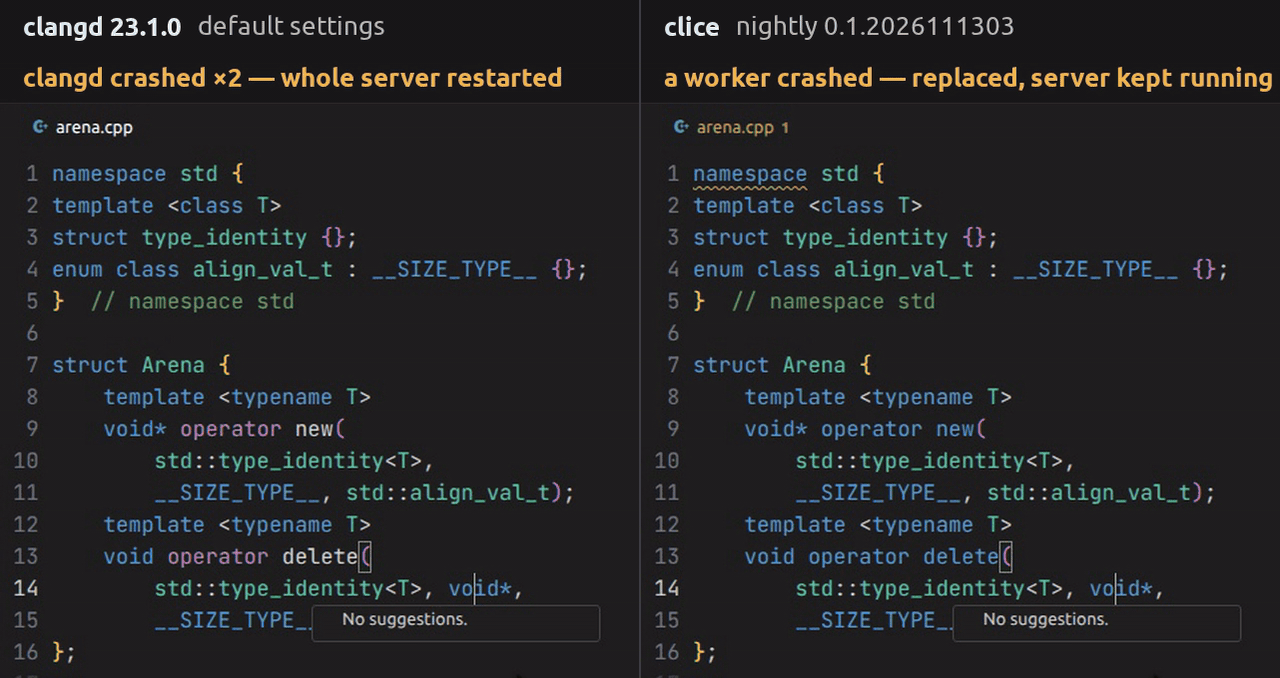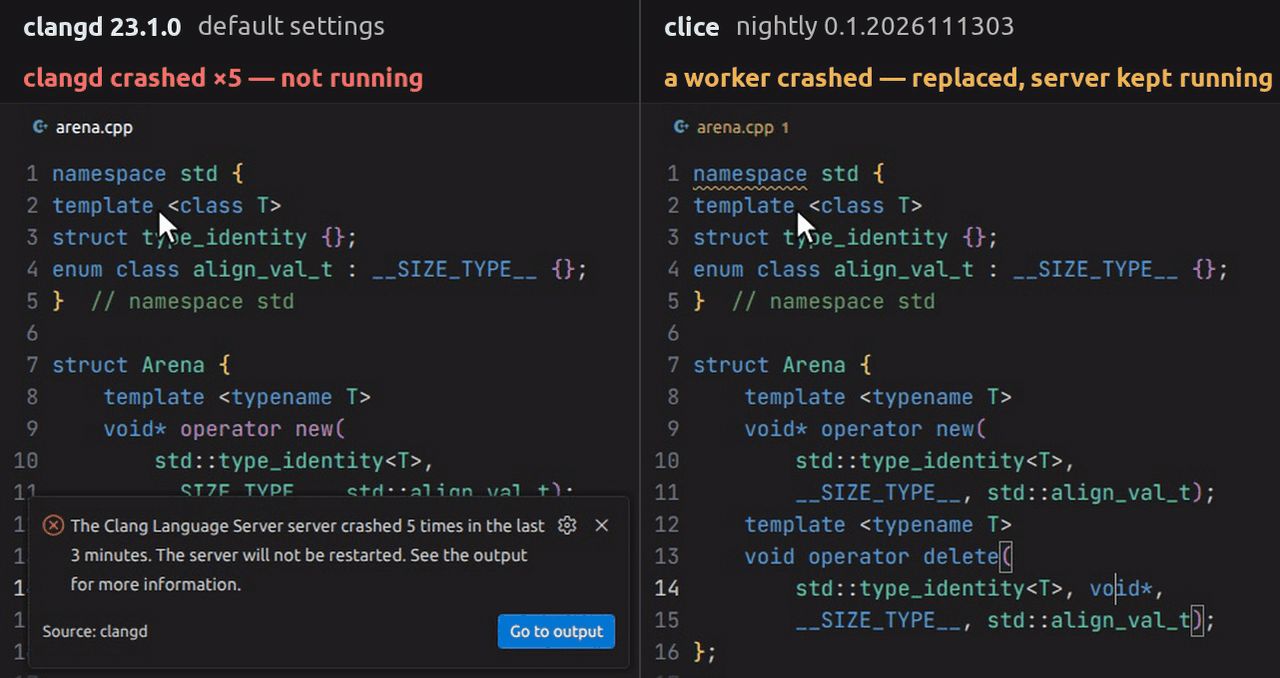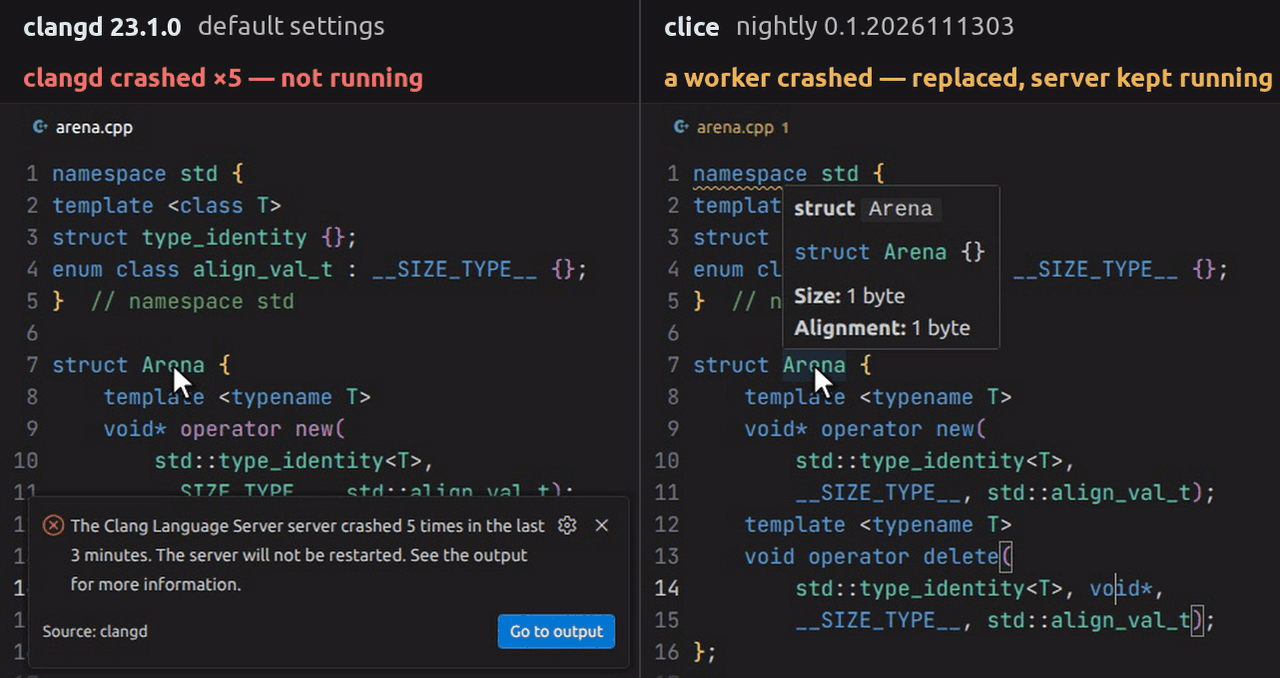
- Multi-process compilation: clice compiles code in a process pool modeled after modern web browsers, whereas clangd uses multithreading. Why multiple processes? Because C++ is simply too complex, and on certain corner cases the compiler can easily crash or leak memory. That is especially true for incomplete code in the middle of editing: a huge downstream user base tests compilers on complete code, while very few people test them on half-written code, where the compiler mostly falls back on best-effort heuristics. In clangd, a compiler crash takes down the whole server and forces a restart. In clice, compilation happens in isolated child processes: losing one worker does not affect the rest of the server, so go-to-definition, highlighting, and other services keep working. It also makes it much easier to manage memory usage and schedule compilation priorities, cutting down on unnecessary resource consumption.
- Modules and shared caching: clice has full support for C++20 named modules. All you need is a
compile_commands.jsoncontaining all module files, and clice scans dependencies on its own and lazily builds required modules on demand, regardless of your build system or compiler, with full support for module completion, highlighting, go-to-definition, hover, and more. Built PCHs and PCMs are also cached on local disk for reuse across sessions. By comparison, clangd offers only very limited module support and no persistent cache. - Compilation context: clice has full support for non-self-contained files, and more generally for the concept of a compilation context. You can explicitly pick the active context of a file: a specific compile command for a source file, or a specific inclusion site for a header. When you open a non-self-contained file, clice detects its context automatically, so it works out of the box. More broadly, it also supports grouping compile commands into build configurations, letting you switch between, say, debug and release.
- Better template support: clice implements a DFS pseudo instantiator that infers what many dependent names resolve to without needing concrete template arguments for a full instantiation. When a template has been instantiated once, clice also draws on that instantiation to power language features, such as completing on
autoparameters of a lambda passed to arangescall. On top of that, clice treats a template as a duck-typed interface and each instantiation as one of its implementations, much like a virtual function and its overrides: Go to Implementation on a dependent call inside a template lists the functions it actually calls across every instantiation, and Find References and Call Hierarchy work the same way. - Out-of-the-box experience: Most projects need nothing more than a
compile_commands.json. clice ships with built-in environment probing for 50+ toolchains, covering nvcc, MSYS2, Cygwin, zigcc, and more, automatically handling mismatches between your actual compiler and Clang. You don’t have to manually add piles of compiler flags to a config file the way you do with clangd.
Beyond these main features, clice also fixes a long list of smaller clangd issues that have gone untouched for years across semantic highlighting, folding, hover, and more. If you’re interested, give it a try and see what surprises you find.
Overall, clice surpasses clangd in ease of use, feature support, and performance. You can install the clice extension in VS Code and other editors and start using it right now.
Command Line
Besides running as a language server, clice can also be used from the CLI to access its language features directly. Currently supported subcommands include:
clice index: Builds a persistent index for the entire project ahead of time and supports resuming interrupted runs, so your editor starts warm as soon as you open the project.clice lint: Built-in clang-tidy runner that checks translation units concurrently across a process pool and merges duplicate diagnostics from headers; pass--indexto reuse the same parse pass to build the index along the way.clice format: A wrapper around clang-format that automatically finds files to format from your config file or CDB and formats them efficiently in parallel.clice command: Shows the effective compile command for a file after rule rewrites and toolchain probing, or convertscompile_commands.jsoninto resolved-cc1 commands for other Clang tools.clice query: Reads the on-disk index directly without starting a server and outputs symbol definitions, references, call graphs, inheritance hierarchies, and file dependencies as JSON.clice refactor: Rewrites source files directly from the persistent index without recompiling, supporting project-wide symbol and macro renaming as well as batch renames in one pass via--spec.clice analyze: Outputs project-structure JSON from the index to guide refactoring; for example,analyze modulesanalyzes module dependencies and cycles across directories and lists code patterns that stand in the way of modularization.clice modularize: Automatically wraps third-party libraries used by a project as C++20 modules without modifying any source files; following the splitanalyzeproposes, it can also rewrite the project’s own code into module units, turning headers into partitions and#includeintoimport. clice used it to modularize itself.
The story behind it
That wraps up the feature tour. Next, I want to talk about the story behind the project, some of its design decisions, and my own thoughts and struggles along the way, especially now, in the age of AI.
Why not improve clangd?
First, why start a new project instead of improving clangd? That is the question I get asked most often. There are several reasons.
I discussed some of them in my earliest post, and today those problems are even easier to see firsthand:
- Maintenance and staffing: At root, clangd has been effectively unmaintained since around 2024. That sounds surprising. How could a tool used by hundreds of thousands of developers have no one maintaining it? I stumbled onto this fact in 2024 when I was getting ready to submit a PR to clangd for better code completion inside templates. From what I understand, it ties back to a shift in Google’s C++ strategy. Before that, clangd was maintained mainly by several Google engineers, and around 2024 Google started scaling back its investment in C++ (Clang); clangd was deemed good enough for Google’s internal needs, and those engineers were reassigned elsewhere. Since then, clangd has lacked any real long-term maintainers. Only Nathan Ridge has been answering questions unpaid in his spare time, purely out of passion, and one person only has so much bandwidth, making it nearly impossible to handle large PRs. That is why clangd’s C++20 modules PR dragged on for nearly a year, and even today it still isn’t really usable on large projects, with plenty of flaws and nobody working on them. Earlier this year, in 2026, Clang’s lead maintainer Aaron Ballman recognized the problem and posted a call for help on the community forum, saying clangd is very close to unmaintained, with a heavy backlog of PRs and issues, and hoping to find new community maintainers; otherwise clangd could eventually be removed from the LLVM project.
- Scale of the code changes: As mentioned at the start, clice introduces many new architectural ideas, such as multi-process compilation. Implementing those inside clangd would come close to rewriting clangd. Nobody is going to review and accept changes of that size. Self-hosting with modules would also require sweeping changes to LLVM’s build system, which I will go into in detail when I introduce xclang later.
- LLVM repository constraints: clice relies on a lot of third-party libraries for better performance and user experience, such as
libuv,simdjson, andtomlplusplus. To keep builds simple, LLVM requires the repository to remain self-contained, so pulling in that many third-party libraries is out of the question. You would either have to rewrite and port them into LLVM or put up with worse ergonomics and lower performance. On top of that, a language server is not a standalone project: it also includes extensions and adapters for different editors. Keeping them in the same repo as the server makes maintenance much easier, and LLVM would be just as unlikely to accept that editor code (spanning Rust, Lua, TypeScript, and so on).
For long-term maintainability and our core goals, a separate repository was unavoidable.
So in mid-2024, I started looking into how to design and write a new language server. At the end of 2024, I published Design and Implementation of a New C++ Language Server, setting out clice’s core goals and kicking off development in earnest.
How did we get here?
Next, let’s talk about how clice was built. How did it get to its current state?
Over the past two and a half years, at a rough guess, I have put nearly 3,000 hours into this project. Even that number doesn’t really tell the story, because clice became part of my life. It was always on my mind, like eating or sleeping: there wasn’t a moment when I wasn’t turning over some problem related to it.
Development broke down into roughly four stages:
Mid-2024 to early 2025: I spent this period studying Clang and clangd’s codebase and internals. Anyone who has looked through my older blog posts will know I am a longtime template metaprogramming enthusiast, familiar with C++ and its implementation details down to language-lawyer territory. During this phase I settled on clice’s core goals and overall design, and put together an initial demo. I was a third-year undergrad at the time: I would wake up and start coding right away, skip lunch, walk out to the McDonald’s outside the campus gate when I got hungry, and put in 8 to 10 hours a day.
Early 2025 to early 2026: I originally expected to ship a usable version of clice fairly quickly during this stage. Instead, progress went much slower than I expected, and it remained a long way from production-ready. Looking back, there were a few main reasons:
- Above all, time. I had assumed I would keep putting in 8 to 10 hours a day like before. My undergraduate major was chemistry, though, and everything I knew about programming was self-taught. Even though I had plenty of C++ experience and had participated in GSoC, I lacked specific “domain knowledge.” To find a job, I spent most o
Comments
No comments yet. Start the discussion.