Developer News
Curated signals for developers. Updated hourly.

Your LLM Capacity Plan Is Lying to You: Inside vLLM Overload Traces
During an overload experiment on vLLM, the engine's own prompt token counter missed a third to half of every prompt token it computed. Requests that were later aborted had already burned 79 to 85 percent of their prefill work before anyone cancelled
Announcing Long-Context Training on TPUs with MaxText Context Parallelism
Google Cloud's MaxText framework now supports long-context training up to 14 million tokens on Cloud TPUs by implementing four context-parallel strategies: All-gather, A2A, P2P, and USP. Powered by the Tokamax Splash Attention kernel, these strategie

Building a WhatsApp AI agent for a UAE business: scope, Meta pricing, hand-off and what to test before launch
In the UAE, a lot of sales conversations no longer start with a form or a phone call. They start with a WhatsApp message, often late in the evening, often in a mix of Arabic and English, and often from someone who has messaged two or three competitor

Your AI Assistant Is Only as Private as Your Retrieval Layer
Why retrieval-augmented generation turns access control into an inference problem, and what developers can do about it. Most teams building AI features start with a simple goal: connect a language model to the company’s data so people can ask questio

Flightpath: a live view into your Claude Code session
Have you ever wondered what Claude Code does behind the scenes when you give it a prompt in the terminal? What goes on inside it? What tools does it call? Which hooks are being called? That was the exact question I had a few days ago. The day the ide

From policy PDF to runtime: enforcing AI governance on every agent call
There's a gap between having an AI usage policy and enforcing it. The document says "the support agent doesn't access financial data". But who guarantees that on call #4,385, at 2 a.m., when nobody is watching? Governance that lives in a PDF is inten

AGENTS.md: the one file that briefs the agents on our repo
I build Yonto Player, a media player for your own library on Android TV, phones and tablets, with AI coding agents. In my experience agents start every session knowing nothing about the repo, so the first thing they read decides a lot of what they do

The Watt-Per-Token Era: Why Energy-Efficient Inference Is the Next Core Developer Skill
For the last few years, the AI conversation has been about capability: bigger models, longer context windows, better benchmarks. But if you’ve shipped anything with an LLM in production, you’ve already met the other constraint: every token costs some
Vulnerability that lets hackers SSH into Linux devices is under active exploitation
"*sshole" poses a serious threat to Internet security.

The backlash about data centers might really just be about electricity
This story originally appeared in The Algorithm, our weekly newsletter on AI. To get stories like this in your inbox first, sign up here. As voters went to the polls across the US last week, I was in Ashburn, Virginia, part of what’s known as Data Ce
Extending LLDB to Debug Applications That Span CPUs and GPUs
We built a vendor-neutral accelerator plugin architecture in lldb-server for debugging applications that span CPUs and GPUs. It separates shared debugger infrastructure from hardware-specific device control. The design represents the CPU and GPU as s
Claude Code is accidentally exposing secrets all over GitHub
"Do not ask again" prompt leads to passwords, API keys, and more being shared.

dature: type-safe configuration through plain dataclasses
A deployment complains that port in production is 9090, while defaults.yaml says 8080. Was it override.yaml , an environment variable, or a Kubernetes ConfigMap? Without the right tooling, finding out can eat half a working day. I've been writing Pyt

The Profiler We Weren't Allowed to Have: 72 Hours of Zero-Dependency Rust at Speed Demon 2026
One lock we didn't even know was contended cost us 8.6 milliseconds - on a track whose entire run, by the end, was 27. That's close to a third of our whole budget, hiding behind a registry that looked completely fine on every machine we could afford

Is Claude Opus 5.5 Nerfed? Claude Code Ignores Your effortLevel. How to Fix It
One Hacker News commenter says their Fable workflows went from a "~85%" success rate to "~10%" about two weeks ago. Another says Opus 5.5 is "suddenly fumbling basic tool calls" and failing to finish tasks even at high effort. A third says nothing ha
‘It feels like malware’: This Chrome extension redirects your web searches to monetized results and was promoted by a VPN with 50 million downloads
Because free VPNs need to make money somehow…

AWS Lightsail pricing in 2026: what each bundle gets you, and the catches
AWS Lightsail is the "simple" corner of AWS: fixed monthly bundles instead of EC2's per-second, per-gigabyte meters. It's a good product. But "simple" hides a few things worth knowing before you pick a bundle. Here's what each Linux bundle includes (

What a 70% vs 90% prompt cache hit rate does to an AI agent’s bill (72 models priced)
An agent sends the same long prefix on every step: system prompt, tool definitions, the files it has read, the conversation so far. Most of it is already in the provider's prompt cache from the step before. How much of it is, the cache hit rate, ends

“Hindsight Stopped My On-Call Agent From Repeating a Failed Fix”
"A practical incident-triage design that remembers failed fixes, not just successful ones, so an on-call agent learns from real operator feedback." Hindsight Stopped My On-Call Agent From Repeating a Failed Fix At 03:47 UTC, billing-api threw HikariP

Hindsight Remembered the Defect. SQL Checked the Evidence.
Hindsight Remembered the Defect. SQL Checked the Evidence. An AI agent remembering a previous manufacturing failure sounds useful. But what happens when it remembers the right symptom and associates it with the wrong root cause? That was the engineer

How I Tested Hindsight Memory Without Fooling Myself
How I Tested Hindsight Memory Without Fooling Myself An agent with memory looks smarter in almost any demo, because you pick the example where it remembers something. We wanted a test that could have said no. On accuracy, it did: after 120 training r
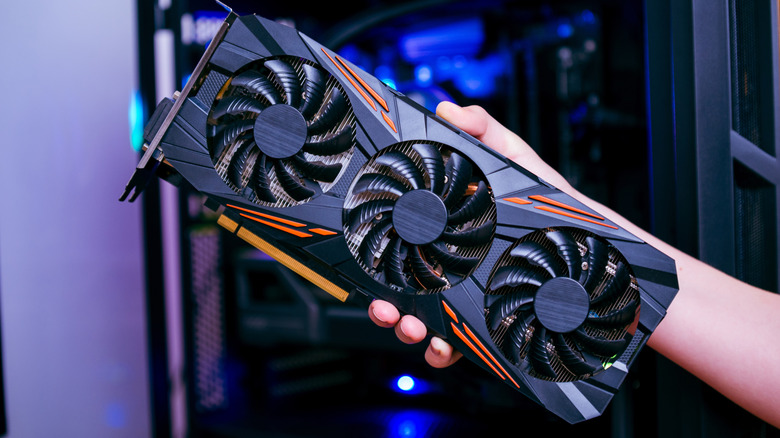
What hardware does your PC need to run a local AI model?
The kind of AI models you can run depends on your machine's power. Let's unpack what your everyday PC will need, and how much it will cost you.

When "Not Found" Doesn't Mean "Never Happened"
Verified on 2026-11-09 against strands-agents 1.63.0, Python 3.11 and Bedrock in us-east-1 . Every number below came out of a run, and the scripts live in usecases/05-reservations-fencing/src/ with raw output in evidence/ . The model in the agent exp

Simulating Traffic for an OCR Service: Part 1
TL;DR For OCR-like services, docs per second, rather than RPS is a key metrics to plan capacity for. Look at the hours when users are busiest - in our example morning p99 is twice the all-day p99. The simulation methods like Monte Carlo can give a wo